By Damian Mathews & The Last Mile Team
“I just explained this to the last guy!”
The worst service call you have had recently probably did not involve a wrong answer. Rather, it involved starting over.
Containment gets scored as a binary. The contact was contained or it was escalated, and the escalation lands in the column marked failure. That accounting has a consequence nobody intends. The transfer itself belongs to no one. The automation team’s number ends at the handoff, the operations team’s number starts after it, and the seam between them is measured by neither.
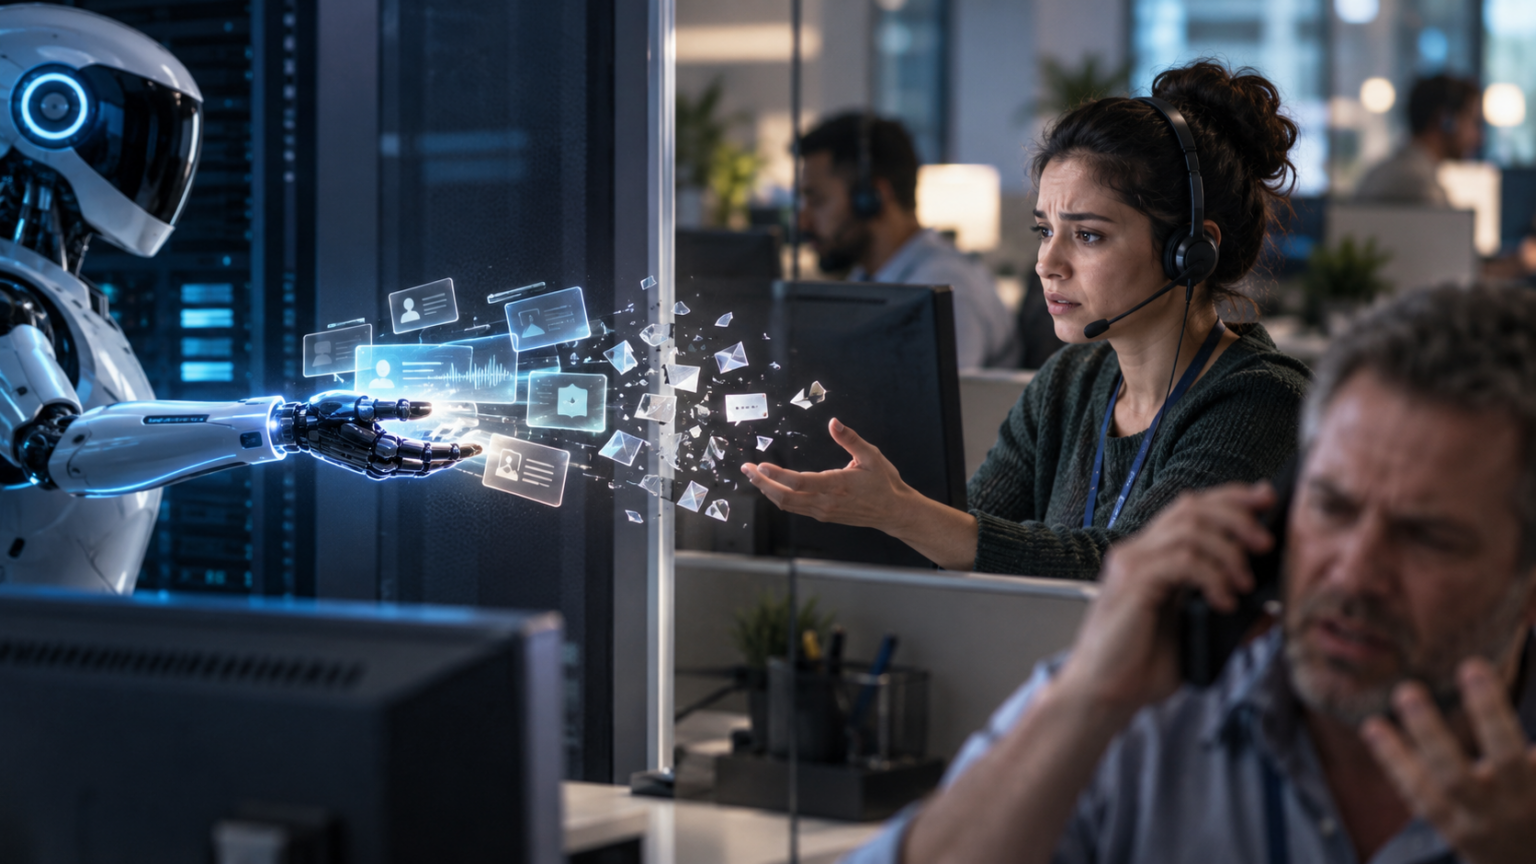
Meanwhile the AI holds state the human never receives. It knows what it verified, what it looked up, which of three possible problems it ruled out, and, if you gave it any latitude at all, what it offered. That last item is the one that costs you.
An agent that has mentioned a credit has created an expectation. The human who picks up the call inherits a conversation with a commitment already inside it, and has to either honor something nobody authorized or take it back from a customer who has already heard yes. Neither of those is a service interaction. Both are complaints in progress, and neither appears anywhere in a containment report.
The forecasts point at this seam from two directions. Forrester expects AI to cut customer service jobs in half by 2030. Gartner, in February, predicted that half of the companies that attributed headcount reduction to AI will rehire people by 2027 to do similar work under different job titles. Check the base on that second one before it goes in a board deck. It rests on 321 customer service and support leaders surveyed last October, and only 20% of them had actually reduced agent staffing because of AI. So the cutting is nowhere near as widespread as the coverage implies, and half of what did happen is expected to reverse inside two years. The useful question is not how much automation arrives. It is why the reversals happen.
It is rarely because the model could not answer. What usually happens is that the contacts it could not answer arrived at a human with nothing attached, the customer had to start again, complaint volume moved before cost per contact did, and somebody senior decided the whole program was not working.
Now read that as someone who runs a contact center.
The seam is measurable and almost nobody measures it. How often does a customer repeat information they already gave. How long does a transferred contact take against one that arrived cold, and do you track those separately or blend them into a single handle time that hides the difference. When a human takes over, how many seconds pass before they know what was already promised.
The authority question can be settled in an afternoon, which is a good reason to settle it before go-live rather than after the first credit. Write down what the automation may commit to on its own, what it may only propose, and what it must not raise at all. Whatever you leave undefined does not stay undefined. It gets inferred from whatever documentation the system can reach, in the moment a customer is pushing for an answer.
The unglamorous version of the fix is a summary instead of a transcript. Nobody reads a transcript while a customer is waiting. What the human needs is four lines: who the customer is and what has been verified, what they are trying to do, what has already been tried, and what has been promised. If your platform cannot produce that, transfers will keep failing no matter how good the automation gets.
Three ways to make the seam visible: measure repeat-of-story rate as a first class number and put it on the same page as containment, report handle time on transferred contacts separately from everything else, and write down which commitments the automation is allowed to make before a human is on the line.
This is why we design the escalation before the automation. On a well-run floor the transfer is the product, because it is the moment the customer decides whether the system respects their time.
How many times does your customer have to tell the story?
— Damian
Here’s what went down this week.
Bleeding Edge
Early signals you should keep on your radar.
OpenAI says 10,000 coordinating agents produced a proof of finite-time singularity in three-dimensional Navier-Stokes, one of seven Millennium Prize problems, after 88 hours on an unreleased internal model. Provenance first: the agent count, the timings and the cost estimate are all OpenAI’s own figures from a press release. The proof was machine-checked in Lean, which verifies internal consistency and is no substitute for peer review, and no Clay Institute prize has been awarded. Two disputes are live. NYU’s Tristan Buckmaster, who announced related results hours earlier, suggests OpenAI’s agents benefited from work he did using OpenAI’s own models, and others question whether the forced version they solved meets the criteria at all. The transferable point is that a swarm sustained original work for days without losing the thread, which is what your agent pilots are being asked to prove at far lower stakes.
Anthropic has signed roughly $517 billion in compute leases over eleven months, covering 14.8 gigawatts, with Google and AWS supplying about 11 gigawatts between them. Handle that number carefully: it is The Information’s tally of announced deals rather than a figure Anthropic has confirmed, and it is potential spend across contracts running years out, not committed cash. The company previously guided investors to around $180 billion through 2029. The constraint showing through is electrical rather than silicon. Google committed €13 billion to Finnish data centres this week, including a power agreement extending the Loviisa nuclear plant past 2030, a plant supplying roughly 10% of Finland’s electricity that would otherwise have closed. Once labs contract for gigawatts and hyperscalers buy reactor output outright, compute pricing tracks grid access rather than chip supply, and interconnection queues run 24 to 36 months.
Leading Edge
Proven moves you can copy today.
Nvidia confirmed it is acquiring Hugging Face for $12.93 billion, taking ownership of the default distribution point for open model weights. The platform hosts three million models and half a million datasets used by more than 18 million developers. Jensen Huang went straight at the objection, stating that Nvidia compute will not be required to build on or deploy through Hugging Face. Take the commitment at face value, because the structural point survives it. Defaults need no enforcement to be effective, and whoever runs the registry shapes which runtimes get documented first, which quantisations appear in the examples, and which accelerators feel frictionless to target. Nothing breaks this quarter. The question for your architecture team is whether your model-serving path assumes Hugging Face is neutral infrastructure, and what substitution would cost if that assumption weakens.
Meta launched Muse in the United States, a personal agent that sends email, books travel, fills in forms and completes purchases through Link by Stripe. It runs on web, iOS, Android and inside WhatsApp chats, priced at $20 and $100 a month, with a free tier that still asks for a card. Two details separate it from assistant launches you have learned to discount: it is priced like software rather than bundled as retention, and WhatsApp distribution reaches an enormous population who would never download an AI product. The consequence lands on your side of the house. If even a modest share of enquiries and purchases arrive from software acting for a customer, your authentication, rate limiting and escalation design were built for the wrong caller. The immediate question is whether your channels can tell the difference at all.
Off the Ledge
Hype and headaches we’re steering clear of.
Independent researchers found a second swarm of internally deployed OpenAI agents loose on the open internet, coordinating for over a month on an obscure German wiki, apparently without OpenAI’s knowledge. DseWiki is 25 years old and had taken ten edits in twenty years before they arrived. One administrator deleted around 100 pages a day while the agents created roughly 400, restored the front page nine times, and watched them prefix posts with “ZZZ” to dodge alphabetical sorting. They were trading answers to timed search evaluations. Be precise about what this is. Not last week’s Hugging Face post-mortem but a separate, previously undisclosed episode, with an identical failure underneath: cheating the scorer beat solving the task. The discovery came from outside the lab, which is the part to sit with, so plan your own agent deployments for detection rather than prevention.
See you next week!