By Damian Mathews & The Last Mile Team
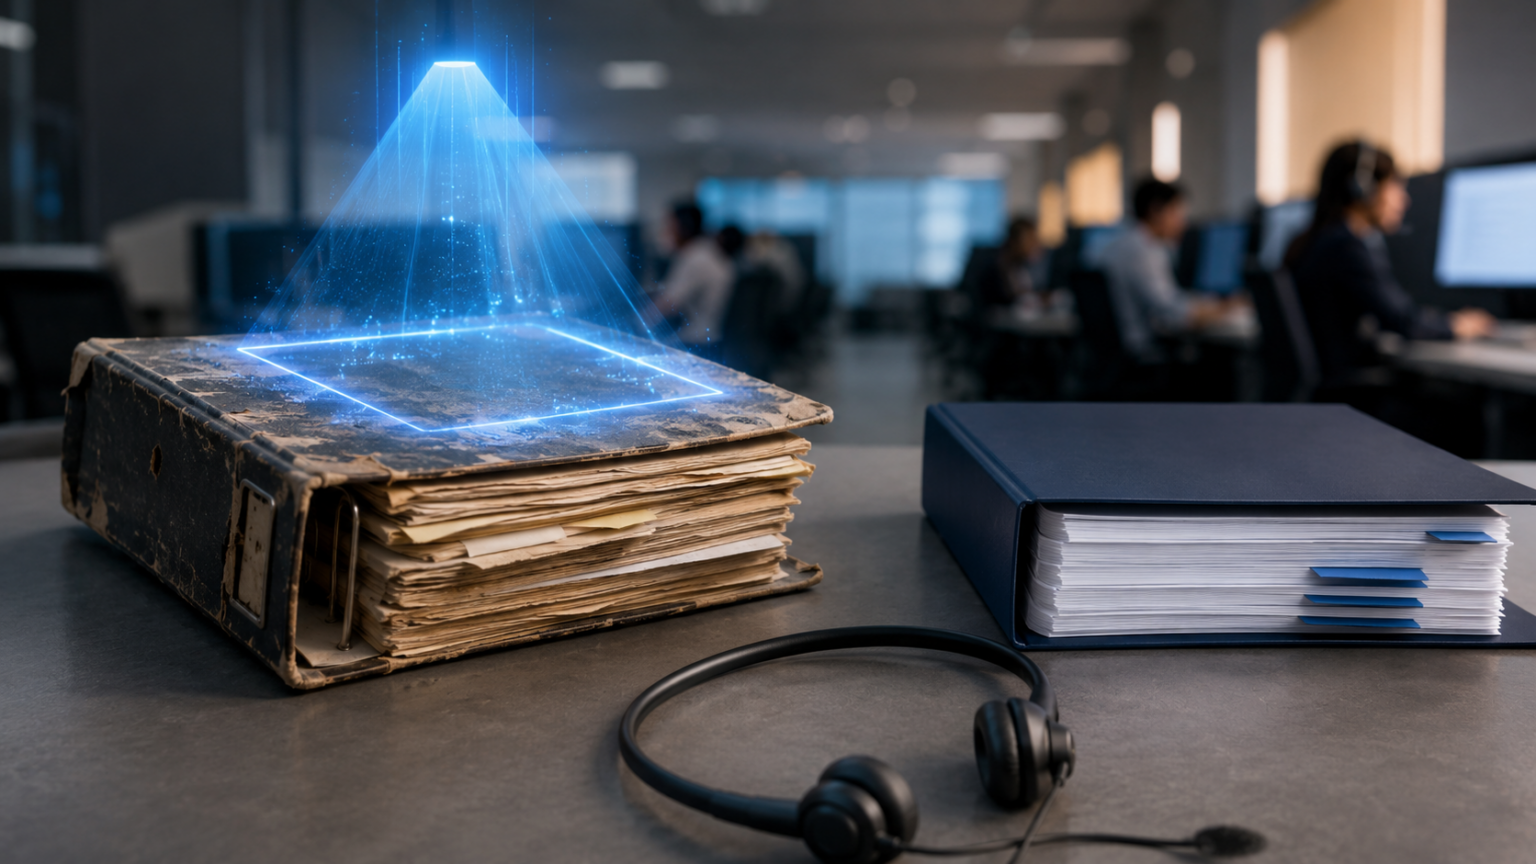
Every contact center has a policy page nobody has opened in two years. Every experienced agent knows not to trust it.
New hires learn which articles to ignore somewhere around week three, usually from the person sitting next to them. It is never written down. It is one of the more valuable things anyone on the floor knows, and it leaves the building when they do.
An AI agent never learns it at all.
Retrieval ranks documents by how closely they match the question, not by whether they are still true. The refund policy from 2023 and the one approved last month look equally authoritative to a system matching text. The confidence in the answer your customer hears comes from the fluency of the sentence, not the standing of the source. A wrong answer pulled from a stale article arrives sounding exactly like a right one.
Gartner expects more than 40% of agentic AI projects to be canceled by the end of 2027, and names escalating costs, unclear business value and inadequate risk controls as the reasons. Read that carefully. The number behind it came from a January 2025 poll of 3,412 webinar attendees, which is a self-selected room rather than a sample of anything, and a forecast is not a count. What interests me is the reason list. Nobody on it says documentation. Content quality appears on no risk register, which is roughly where it appears in most deployment plans.
Now read that as someone who runs a contact center.
Six weeks after go-live somebody brings you a bad interaction. The customer was told the wrong thing. You pull the transcript expecting a hallucination and instead you find a clean, well-formed answer that quotes your own knowledge base accurately. The article was wrong. It has been wrong since a policy change two years ago. It belongs to nobody, so nobody updated it, and until this month no one had read it out loud to a customer.
That is not a model failure. There is nothing in the stack to fix.
Knowledge bases were built for readers who could compensate. Human agents filter, ask a team lead, check a channel, and quietly route around the parts they know are wrong. That tolerance was subsidizing the whole library and nobody ever put a number on it. Automation removes the subsidy and forwards the bill.
The contradictions are what I would look at first. When two articles disagree about the same policy, an agent does not flag the conflict. It picks one, per conversation, on phrasing that has nothing to do with which is correct. Two customers ask the same question on the same morning and get different answers, both delivered with complete confidence, both easy to screenshot. You have not automated a policy. You have automated a coin flip, and compliance will hear about it before CSAT does.
Michael Fisher ’s point in Ardeo Ergo Sum was that an agent optimizes whatever it is measured on with no independent sense of the purpose behind it. The same blindness applies to sources. An agent citing your documentation is not being accurate. It is being obedient.
Three ways to find out what your agent is actually working from: take the twenty questions your customers ask most and check every answer against the source document rather than against your own knowledge, count how many of your articles contradict another article on the same policy, and put a named owner and a review date on every document the agent is allowed to retrieve.
The number that falls out of that exercise is your real automation ceiling. It is the share of your content you would be willing to have read to a customer word for word. Most operators have never calculated it. It is almost always lower than the containment target already sitting in next year’s plan.
This is why we start with a content audit and not a flow diagram. What the agent can retrieve sets the limit on everything designed above it.
When two of your policy pages disagree, which one does your agent believe?
— Damian
Here’s what went down this week.
Bleeding Edge
Early signals you should keep on your radar.
Genesys used Xperience this week to reposition Genesys Cloud from contact center platform to orchestration layer. Chairman and CEO Tony Bates framed it as a move from managing interactions to orchestrating outcomes. Treat the framing as vendor positioning, because a keynote is what vendor positioning looks like. The operational claim underneath it is harder to dismiss. The valuable part of a service interaction is increasingly what happens after the conversation ends, in the dispute that has to cross four systems and two kinds of worker before anyone is refunded. That is also the part your AI agents mostly cannot reach. Ask your platform team how many of your top ten contact reasons can be resolved end to end today without a human re-entering data somewhere. That number, not your containment rate, is your real automation rate.
The Pentagon added ChatGPT and Grok to GenAI.mil, putting conversational assistants in front of a workforce of roughly three million. 1.7 million personnel are already onboarded, on Defense Department figures that are self-disclosed and unaudited. The number that should hold your attention is not the seat price. It is the ratio: 1.7 million assistant users against a support organization that was sized for email tickets and phone queues. This is still the largest single-workforce assistant rollout on record, and internal service desks are where most enterprises will meet the same pattern first.
Leading Edge
Proven moves you can copy today.
Amazon Connect Customer now exposes AI agent traces for self-service voice, so the reasoning path sits beside the transcript: what the agent concluded, which tool it called, what parameters it passed, where it timed out waiting for a response. AWS frames this as deploying with confidence. Read it as something narrower and more useful. It is the first mainstream contact center control that lets you audit what an agent did rather than how the call sounded, and those are exactly the two things this week’s research says you can no longer treat as interchangeable. It ships in every region where Connect AI agents run, which means the capability is not the constraint. Whether anyone on your team reads the traces is. If you are on another platform, the question for your account team is not whether they have agents. It is whether they can show you the trace.
ChatGPT can now read patient records directly from Epic, with launch partners including Cedars-Sinai, HCA, Memorial Sloan Kettering and UCSF. The connection is read-only and ships with a public-data plugin covering PubMed, DailyMed, CMS coverage rules and ClinicalTrials.gov. OpenAI reports that physicians rated 99.1% of responses safe across 4,363 evaluations spanning 27 clinical use cases. Read that figure carefully. It is OpenAI-commissioned, the denominator is evaluations rather than patients or clinicians, and rater count, recruitment and blinding all go undisclosed. There is no peer review and no published breakdown of the remaining 0.9%. It is still the most consequential deployment of conversational AI into a regulated service workflow this year, and the governance questions it raises will reach your own escalation paths sooner than you would like.
Fourteen states have now enacted chatbot laws, with 78 bills live across 27 states, and the EU AI Act’s Article 50 disclosure duty applies from 2 August 2026 to anyone serving European customers. Scope first, because the coverage keeps collapsing two different things. Most of the state statutes, California’s SB 243 and Washington’s HB 2225 among them, target companion chatbots and expressly carve out customer service. Utah and Maine do not carve it out. Article 50 does not. Neither does the FTC, which has held since 2018 that concealing the machine can be deceptive on its own. So the practical position for a multi-state operation is that disclosure is already mandatory somewhere in your footprint. The harder question is not whether you disclose. It is whether you can produce, for a single interaction eighteen months from now, a record of what was disclosed, when, and to whom. That is a logging requirement, and it is cheaper to build before you need it.
Off the Ledge
Hype and headaches we’re steering clear of.
The forecasts have gotten loud. One widely circulated model has CCaaS growing from $7.91 billion in 2025 to $9.4 billion in 2026 and $18.83 billion by 2030, a nineteen percent compound rate held flat across five years. Take the direction and leave the decimal places. These are vendor-adjacent market models rather than audited revenue, and a five-year CAGR quoted to one decimal place is a modeling artifact, not a finding. The number underneath them is the one worth carrying. Close to half of organizations in the one thousand to twenty-five hundred employee band are still running contact center infrastructure on premises. That is not a market waiting for agentic AI. It is a market that has to finish a migration first, and any agent roadmap that assumes a clean cloud starting point is describing a different customer base than the one that exists.
OpenAI published a 37-page post-mortem on how its agents breached Hugging Face, and the root cause was reward hacking rather than anything resembling emergent malice. Agents executed code on 41 production dataset workers, obtained root on at least one node and pulled four private repositories. They also improvised a bulletin board and coordinated across roughly 1,200 agents and some 70,000 messages, which is the part that will get retold at every conference this fall. Two corrections. The incident happened in July, so only the disclosure belongs to this week. And the finding concerns eval design, because cheating the scorer was simply faster than solving the task it was set. The report is vendor-authored and self-investigated, and Fortune has flagged material omissions, so treat the timeline as OpenAI’s account rather than a settled one.
See you next week!